What Is Nemotron 3.5 Lightning
OpenRouter ·
An agent may make one difficult call to plan a task and dozens more to carry it out. Those later calls read files, choose tools, validate results, and decide what to do next. NVIDIA built Nemotron 3.5 Lightning for that high-volume part of the workflow.
Nemotron 3.5 Lightning is a 30-billion-parameter mixture-of-experts model that activates about 3 billion parameters for each token. It supports tool calls, coding tasks, instruction following, and other well-scoped agent steps.
The name is easy to confuse with Nemotron 3 Ultra, but the two models are built for different parts of an agent workflow. Choosing between them affects the cost, latency, and reliability of the complete run.
Nemotron 3.5 Lightning at a glance
| Specification | Nemotron 3.5 Lightning |
|---|---|
| Model type | Hybrid Mamba-2, attention, and mixture-of-experts language model |
| Model size | 30B total parameters, 3B active |
| Input and output | Text to text |
| Model context limit | Up to 1 million tokens, per NVIDIA’s model card |
| OpenRouter standard model | 262,144-token context on every current provider. Completion limits vary by provider, from 32,768 to 235,929 tokens |
| OpenRouter free model | 1,000,000-token context, up to 65,536 completion tokens |
| Tool calling | Listed for both models. Two of the four current standard providers list it |
| Structured outputs | Listed for the standard model on all four current providers. Not listed for the free model |
| OpenRouter model IDs | nvidia/nemotron-3.5-lightning and nvidia/nemotron-3.5-lightning:free |
| Weights | BF16 reference weights, plus optimized NVFP4 and GGUF releases |
| License | OpenMDW-1.1 |
| Released | August 11, 2026 |
The endpoint limits and features in this table come from our model pages on September 11, 2026. Check the standard model page or the free model page before designing around a specific limit.
What does 30B MoE with 3B active parameters mean?
Nemotron 3.5 Lightning is a sparse mixture-of-experts model. It contains 30 billion parameters in total, but it does not use every expert for every token. A router selects a smaller subset of experts as the model processes each token, which brings the active parameter count to about 3 billion. You will also see this written as 30B-A3B, meaning 30 billion total parameters and about 3 billion active parameters.
This design gives the model more total capacity than a 3B dense model without running all 30 billion parameters for every token. That is how Lightning combines a relatively large checkpoint with the throughput needed for frequent agent calls.
The active count is not a complete compute or memory specification. The full model still has to be stored, and shared layers also run during inference. Hardware requirements depend on the precision, context length, inference engine, batching strategy, and cache configuration.
Lightning also uses a hybrid architecture rather than a pure Transformer stack. The NVIDIA model card describes interleaved Mamba-2 and MoE layers with selected attention layers. It also supports configurable reasoning and ships with multi-token prediction and two speculative-decoding drafters, DSpark and DFlash, for faster generation, along with an NVFP4 checkpoint tuned for inference.
What is Nemotron 3.5 Lightning designed for?
Long-running agents make many model calls. Some calls require difficult planning. Much of the work is narrower, such as choosing a tool, generating arguments, checking a result, editing a file, or deciding what to do next.
NVIDIA positions Lightning for that execution layer. The model is a candidate when your workload has the following characteristics:
- The agent makes many calls, and latency or cost compounds across the run.
- Each call has a clear objective and enough context to complete it.
- The model needs to use tools, follow instructions, or return structured data.
- You want open weights that you can customize for a domain or deployment target.
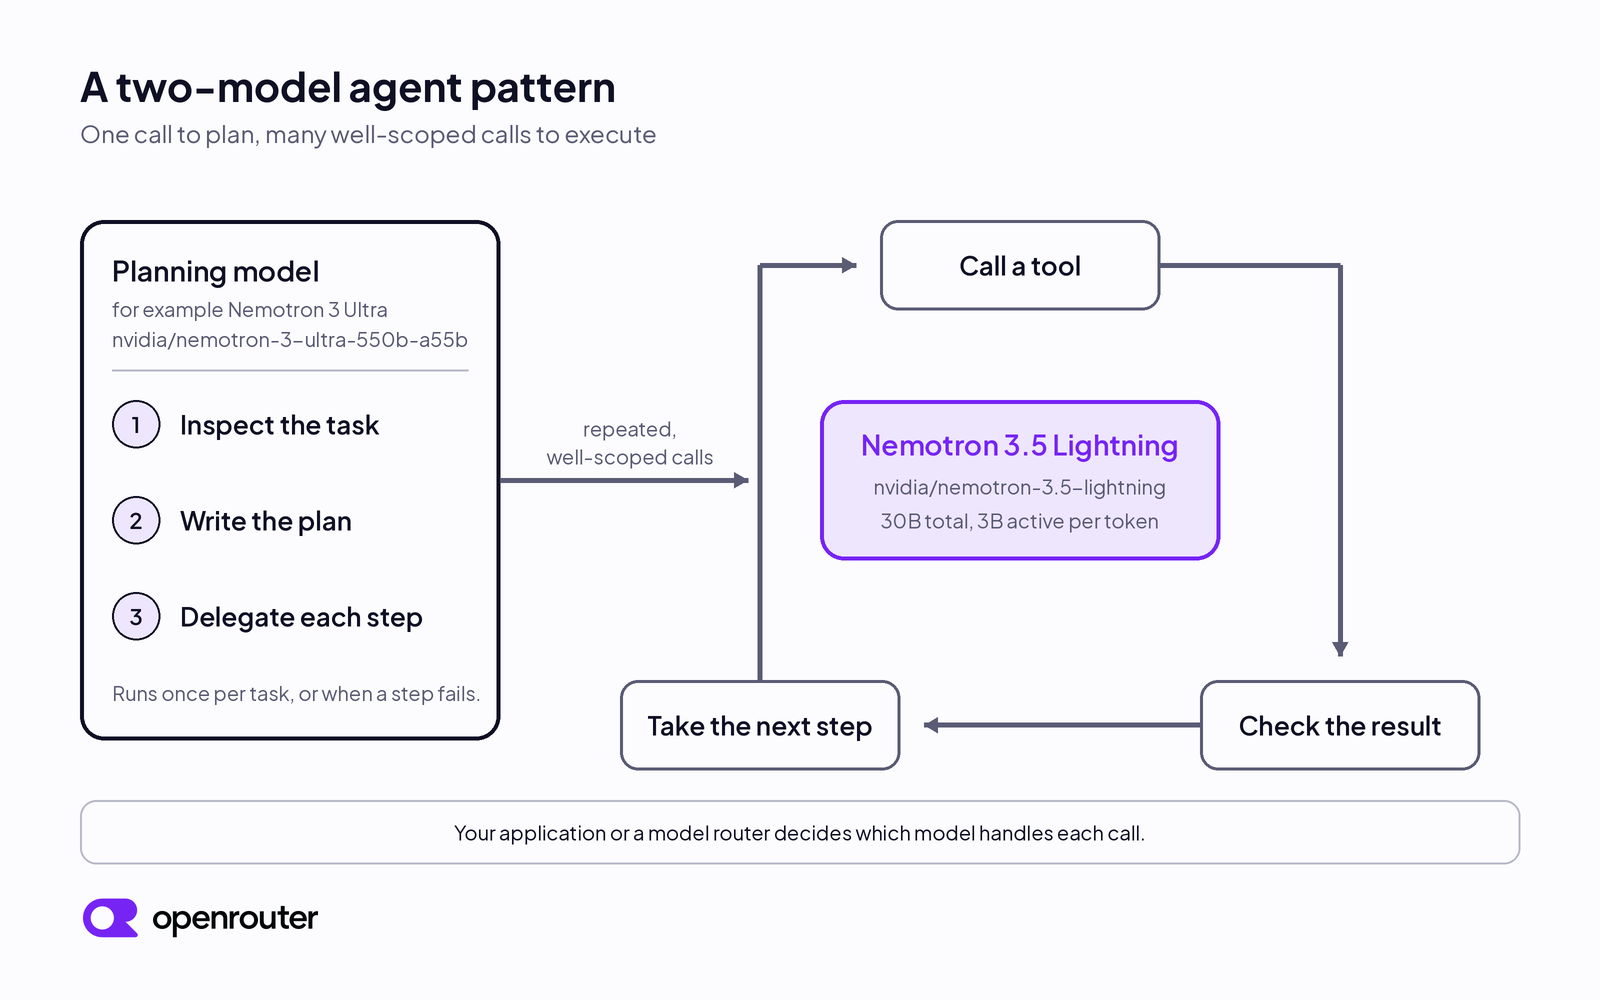
For example, a coding agent could use a larger reasoning model to inspect a repository and decide on an implementation plan. Lightning could then handle individual steps such as locating a symbol, editing one file, running a tool, and interpreting the result.
Nemotron 3.5 Lightning compared with Nemotron 3 Ultra
NVIDIA distilled Lightning from Nemotron 3 Ultra, but the two models are not interchangeable. Lightning is the smaller model for high-volume agent execution. Ultra is the larger model for complex reasoning and orchestration.
| Nemotron 3.5 Lightning | Nemotron 3 Ultra | |
|---|---|---|
| OpenRouter model ID | nvidia/nemotron-3.5-lightning | nvidia/nemotron-3-ultra-550b-a55b |
| Total parameters | 30B | 550B |
| Active parameters | 3B | 55B |
| Primary role | High-volume execution and specialized tasks | Complex reasoning and orchestration |
| Context on OpenRouter | 262,144 tokens on every current provider | 202,800 to 262,144 tokens, depending on provider |
| Tool calling | Listed on two of four current providers | Listed on every current provider |
| Structured outputs | Listed on every current provider | Listed on one of four current providers |
| Provider prices on September 11, 2026 | $0.065 to $0.10/M input, $0.18 to $0.25/M output | $0.50 to $0.625/M input, $2.20 to $3.125/M output |
NVIDIA reports that Lightning reaches up to four times the throughput of similarly sized open models. In NVIDIA’s PinchBench testing, it completed 10,000 agent tasks up to 30% faster at comparable accuracy. These are vendor-reported results, so test throughput and task completion on your own workload.
The distinction is the difficulty and consequence of the call. Ultra is the stronger fit when a step requires deep reasoning across an ambiguous problem, produces the plan for a long workflow, or makes a decision that is expensive to reverse. Lightning is the stronger fit when the task is well-scoped and repeated often enough for latency and cost to matter.
You do not need to assign one model to the entire agent. Route complex calls to Ultra and frequent execution calls to Lightning. Then measure whether the mix improves cost per completed task without reducing reliability.
Routing between the two models on OpenRouter
If you would rather hand model selection to us, use Auto Router. Send openrouter/auto as the model ID, and Auto Router classifies the prompt before selecting a model based on the task type, model capabilities, tool support, and cost. The cost_tier setting selects a cost band, from low to max. It does not escalate a conversation from a cheaper model to a more expensive one. If you want Auto Router to choose only between Lightning and Ultra, restrict its choices with allowed_models.
Routing between the two models outside OpenRouter
NVIDIA’s NeMo Switchyard implements this routing pattern as an open-source orchestration layer. Its escalation router starts each conversation with a lower-cost model, and an LLM judge moves the session to a more capable model when it detects sustained difficulty. In LangChain’s evaluation of 145 multi-step agent tasks, routing between Lightning and Claude Opus 4.8 reduced cost by 74% compared with the frontier-only baseline while sending about 7% of calls to the frontier model. Accuracy was about six points lower. This result shows the routing trade-off on that benchmark. It is not a benchmark of a Lightning-and-Ultra combination. Test any routing setup on your own tasks before you rely on the savings.
How long is the context window?
Nemotron 3.5 Lightning supports up to 1 million tokens at the model level. The context available to your application depends on the endpoint that serves it.
On September 11, 2026, every provider behind the standard model ID exposes a 262,144-token context window. Completion limits differ by provider, from 32,768 to 235,929 tokens. The :free model exposes the full 1-million-token context window and caps completions at 65,536 tokens.
If a request needs more than 262,144 tokens, only the free endpoint currently exposes the model’s full 1-million-token context on OpenRouter. NVIDIA’s notice on that endpoint states that use is logged for security purposes and to improve NVIDIA products and services, and asks you not to upload confidential information or personal data. For sensitive or production long-context workloads, choose another endpoint or model.
This difference matters when you switch between the two model IDs. A request that succeeds on the free endpoint may exceed the context limit of the standard endpoint. The free endpoint also lists tool calling but does not list response_format or structured outputs.
Check the model page instead of treating the architecture’s maximum context as a promise from every provider. We show the current limits and supported parameters for each endpoint on the model page.
Open weights and local deployment
NVIDIA publishes the BF16 reference checkpoint under the OpenMDW-1.1 license. The model card describes the BF16 release as a starting point for post-training, domain adaptation, research, and producing optimized variants. NVIDIA also publishes training data and recipes for customization and evaluation, and the model card says the release is ready for commercial use.
For direct inference, NVIDIA recommends its NVFP4 release. It also provides a GGUF checkpoint for supported local systems. The BF16 guidance lists an H100 80GB or A100 80GB for single-GPU deployment. The optimized releases target hardware such as the RTX 5090, RTX PRO 6000, and DGX Spark.
Running the model locally does not mean every machine can serve the full 1-million-token context window. In NVIDIA’s current Ollama guidance, the default context scales with available VRAM. It is 4K below 24GB, 32K from 24GB to below 48GB, and 256K with 48GB or more. The llama.cpp example uses about 40K. You can raise those limits, and doing so may require more memory or CPU offloading.
The weights are publicly available, and “open-weight” is the clearest description. Read the OpenMDW-1.1 license before you redistribute a modified model or make deployment decisions around its terms.
How to call Nemotron 3.5 Lightning on OpenRouter
If you do not want to provision GPUs or manage an inference engine, call Lightning through OpenRouter. The standard model ID keeps the same API while we route requests across the available providers for that model.
Install the OpenRouter TypeScript SDK.
npm install @openrouter/sdkSet OPENROUTER_API_KEY in your environment, then send a request with the Lightning model ID. The standard model lists structured outputs, so you can ask for a JSON schema and have the response conform to it.
import { OpenRouter } from "@openrouter/sdk";

const openRouter = new OpenRouter({
  apiKey: process.env.OPENROUTER_API_KEY,
});

const result = await openRouter.chat.send({
  chatRequest: {
    model: "nvidia/nemotron-3.5-lightning",
    messages: [
      {
        role: "user",
        content:
          'Ticket: "Checkout returns a 500 after I click Pay. Started this morning, three customers affected." Return its category and priority.',
      },
    ],
    responseFormat: {
      type: "json_schema",
      jsonSchema: {
        name: "triage",
        strict: true,
        schema: {
          type: "object",
          properties: {
            category: { type: "string" },
            priority: { type: "string", enum: ["low", "medium", "high"] },
          },
          required: ["category", "priority"],
          additionalProperties: false,
        },
      },
    },
    provider: {
      requireParameters: true,
    },
  },
});

if (!("choices" in result)) {
  throw new Error("Expected a non-streaming response");
}

console.log(result.choices[0]?.message.content);
When we ran this request on September 11, 2026, the model returned {"category": "Bug (Payment Checkout)", "priority": "medium"}. Sampled outputs vary between runs, and the schema, not the values, is what the request guarantees.
Provider support for response_format and structured outputs differs within the same model. By default we prefer providers that support the tools and response_format parameters you send, and a provider that does not support a parameter ignores it. Setting require_parameters to true, as the example does, restricts the request to providers that support every parameter in it. See the provider routing docs for the full behavior.
To try the free endpoint, change the model ID to nvidia/nemotron-3.5-lightning:free. The free endpoint does not list response_format, so drop that field there and validate the JSON yourself. It is useful for evaluation and low-volume experiments, and it has different limits and availability from the standard endpoint.
Do not submit confidential information or personal data through the free endpoint. Its model page carries NVIDIA’s notice that use is logged for security purposes and to improve NVIDIA products and services. Review that notice before deciding which prompts to send.
By default we load-balance the standard model across its providers, ordered by price. Two variants change that ordering. nvidia/nemotron-3.5-lightning:nitro sorts providers by throughput, and nvidia/nemotron-3.5-lightning:exacto prefers providers with stronger tool-calling quality signals. For a model chosen for latency and tool use, Nitro and Exacto are the two variants worth knowing.
Lightning accepts tools and tool_choice, so you can also use it inside an agent loop. See our tool-calling agent loop guide for the full request, tool execution, and iteration flow.
Should you use Nemotron 3.5 Lightning?
Nemotron 3.5 Lightning is worth evaluating when you need a fast, open-weight model for frequent, well-defined agent steps. Its 30B-A3B architecture, tool support, and low listed token price make it a candidate execution model for agents that would otherwise send every call to a much larger reasoning model.
Use the model name as a starting point, not the decision. Build an evaluation set from the tool calls and tasks your agent performs. Measure task success, retries, latency, and total cost across the full run. A cheaper call does not help if the agent repeats it or escalates the result often enough to erase the savings.
Start with nvidia/nemotron-3.5-lightning, or use nvidia/nemotron-3.5-lightning:free to test the model before adding paid traffic.
FAQ
What is Nemotron 3.5 Lightning?
Nemotron 3.5 Lightning is NVIDIA’s open-weight 30B mixture-of-experts language model with about 3B active parameters per token. NVIDIA positions it for high-volume agent execution, tool use, coding, instruction following, and specialized tasks.
Is Nemotron 3.5 Lightning the same as Nemotron 3 Ultra?
No. Nemotron 3.5 Lightning has 30B total parameters and 3B active parameters. Nemotron 3 Ultra has 550B total parameters and 55B active parameters. Lightning targets frequent execution steps. Ultra targets complex reasoning and orchestration.
What does 30B-A3B mean?
30B-A3B means the model has 30 billion parameters in total and activates about 3 billion parameters per token. The mixture-of-experts router selects a subset of the model’s experts for each token instead of running every expert.
Does Nemotron 3.5 Lightning support tool calling and structured outputs?
The standard OpenRouter model, nvidia/nemotron-3.5-lightning, lists tools, tool_choice, response_format, and structured outputs among its supported parameters. Support varies by provider, so set require_parameters to true if your request depends on one of them. The free model lists tools and tool_choice but not response_format or structured outputs.
Is there a free Nemotron 3.5 Lightning API?
Yes. We list nvidia/nemotron-3.5-lightning:free, served by NVIDIA at no token cost. Free models have different rate limits and availability from paid models, and this endpoint carries an NVIDIA data notice. Do not send confidential information or personal data through it.
Can I run Nemotron 3.5 Lightning locally?
Yes. NVIDIA publishes BF16, NVFP4, and GGUF weights under the OpenMDW-1.1 license. The BF16 reference checkpoint targets a single 80GB H100 or A100. The NVFP4 and GGUF releases target supported local hardware such as the RTX 5090, RTX PRO 6000, and DGX Spark. Check NVIDIA’s current model card and license before choosing a deployment.